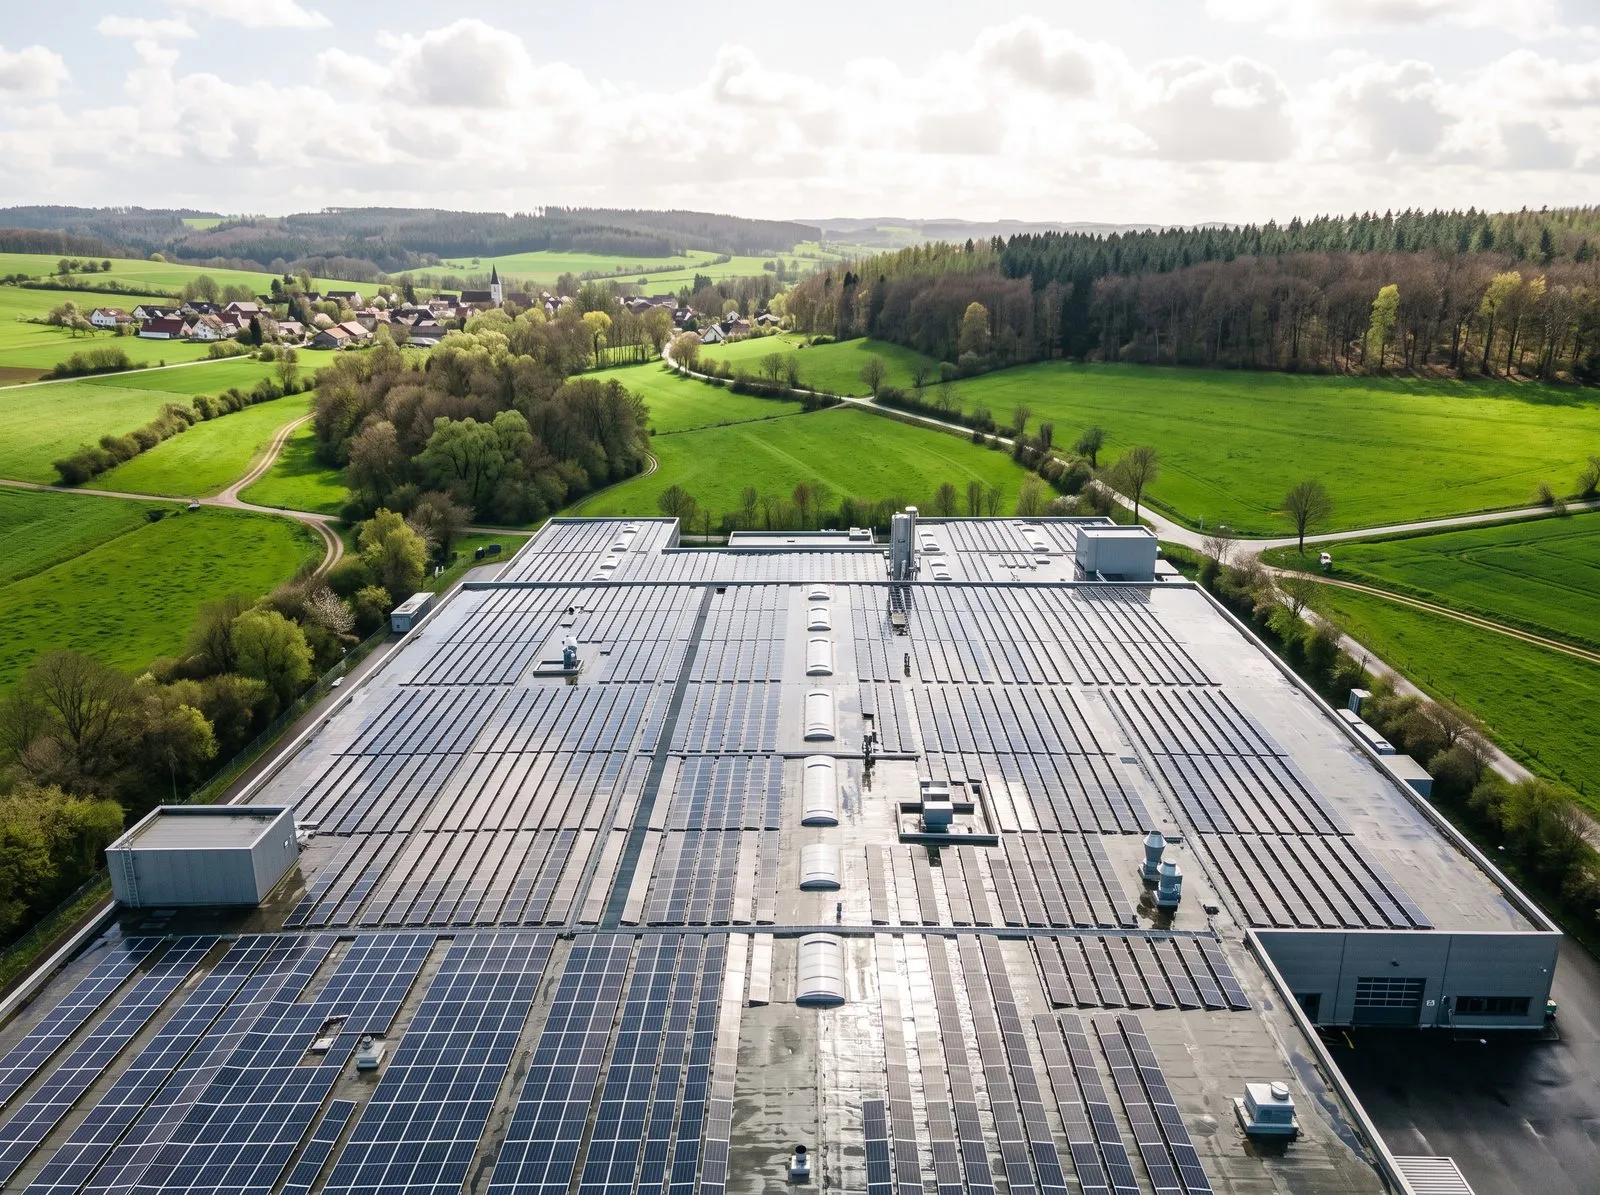
A solar power forecast estimates electrical output, not simply sunshine. The conversion from weather to generation depends on the installation and its operating state. Better forecasts therefore require a coherent chain of weather inputs, asset metadata, measurements and evaluation. The original 2016 article introduced work on improving PV forecasting; the enduring practical question is where an error enters that chain.
Describe the installation before choosing a model
Provide the plant location, capacity definition, module orientation, tilt and relevant inverter limits. A tracking system behaves differently from a fixed installation. Shading and changes to equipment can also alter the relationship between irradiance and production. Record metadata versions so that a change in plant configuration is not mistaken for model drift.
Use the correct solar quantity
Radiation on a horizontal surface is different from radiation on the module plane. A weather input may be a total accumulated over an interval rather than an instantaneous value. Check the field definition and units before converting it into plant output. Temperature affects PV efficiency, while clouds strongly influence the available solar resource. The relative importance of each input depends on horizon and conditions.
Separate production from constraints
An inverter can clip output at high irradiance. Grid limits, curtailment or outages can reduce exported power even when the plant could generate more. Define whether the forecast represents available generation or expected feed-in. Treat measured zeros and missing telemetry differently: a missing observation is not evidence that the plant produced no electricity.
Test the forecast at the operational deadline
Archive forecasts as they were issued. Compare them with measurements at the agreed interval and connection point. Evaluate day-ahead and intraday forecasts separately, and include a simple baseline. Examine errors by season, daylight period and output level. Night-time zeros can make a whole-day average look better without explaining performance during the intervals that matter to a trader.
Use feedback without hiding failures
New production data can help a forecast adapt to site behaviour. That feedback is only useful when measurements are timely and trustworthy. Define how stale, missing or implausible data is detected. Review unusual error periods with operating logs before changing the model. Improvement should be demonstrated on held-out operational data, with delivery reliability and error treatment visible to the buyer.
Match the horizon to available evidence
A near-term update can use recent plant measurements, but a forecast issued earlier cannot rely on them. Satellite, weather-model and telemetry inputs also arrive at different times. Ask which information is used at each horizon and whether it was genuinely available before the decision deadline. This is particularly important when comparing a live intraday service with a historical day-ahead reconstruction. They answer different operational questions.
Investigate errors with a shared record
Choose several difficult periods and place the issued forecast, measured feed-in, weather information and operating events on the same timeline. Look for clipping, abrupt outages, stale telemetry and shifts in cloud timing. An average error score identifies neither the cause nor the correct response. The review should decide whether the problem concerns data quality, plant metadata, conversion or weather prediction. Keep the conclusion and any change date with the dataset so that subsequent improvement can be tested.
Agree acceptance criteria
For a pilot, specify required delivery, target quantity, evaluation subsets and the process for discussing anomalies. Use identical rules when comparing candidates. A provider should be able to explain the test without asking the buyer to assume that every improvement comes from a more complex algorithm. Operational usefulness depends on a forecast that can be received, interpreted and evaluated consistently.